
Resume Parsing
Resume parsing converts resume text into structured fields such as employers, titles, dates, education, skills, and contact information.
Resume parsing is the automated extraction of information from a resume into structured fields. A parser may identify a candidate's name, contact information, employers, job titles, dates, education, and skills so the information can be stored or searched.
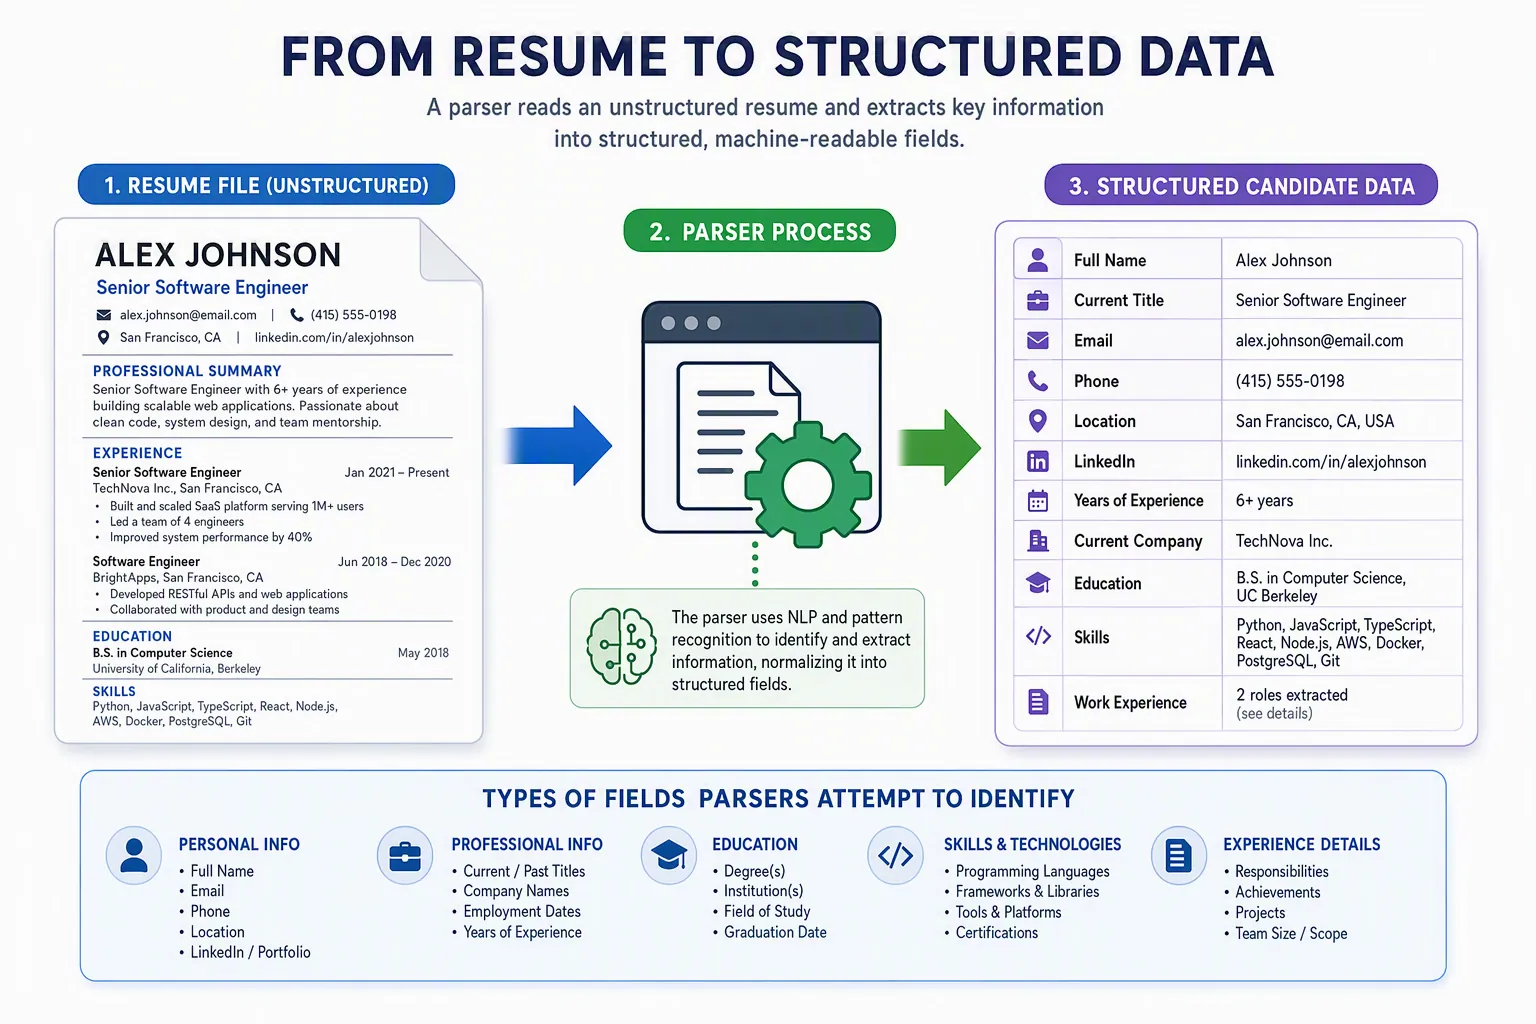
A parser can extract text without deciding whether the candidate is qualified; recruiters, hiring managers, rules, searches, or other systems may use the resulting record later. Different applicant tracking systems and configurations behave differently; formatting affects the result. A file may look correct to a person but produce a confused reading order when important details sit in columns, text boxes, graphics, headers, or footers; a scanned image may contain no accessible text unless optical character recognition is applied; selectable text, familiar headings, consistent dates, and a simple reading order reduce avoidable extraction problems without guaranteeing identical behavior across systems.
For example, a parser may extract a date correctly but attach it to the wrong employer when a two-column layout obscures reading order.
Related concept: What Is An Applicant Tracking System